This example was automatically generated from a Jupyter notebook in the RxInferExamples.jl repository.
We welcome and encourage contributions! You can help by:
- Improving this example
- Creating new examples
- Reporting issues or bugs
- Suggesting enhancements
Visit our GitHub repository to get started. Together we can make RxInfer.jl even better! 💪
Integrating Neural Networks with Flux.jl and Lux.jl
This advanced tutorial demonstrates the powerful combination of probabilistic programming with deep learning in Julia, showing how to integrate a neural network into a probabilistic model with RxInfer.jl.
Julia has two widely used neural network libraries, and they take opposite approaches to where parameters live:
- Flux.jl stores the trainable parameters inside the layer object and updates them in place.
- Lux.jl is purely functional: the layer is only a description of the architecture, and the parameters
psand non-trainable statestare passed in explicitly at every call.
Rather than presenting these separately, this example builds the probabilistic model once and then plugs each library into it through a small adapter. Everything downstream - the free energy objective, the training loop, the plots - is shared, so the only code that differs between the two is the part that is genuinely library-specific. At the end we compare the two results directly.
# Both libraries export names like `Dense`, `setup` and `destructure`, so a plain
# `using Flux, Lux` would make those ambiguous. We import them qualified instead,
# which also makes it unmistakable which API each call belongs to.
import Flux, Lux, Optimisers

using RxInfer, Random, Plots, LinearAlgebra, StableRNGs, ForwardDiff
In this example, our focus is on Bayesian state estimation in a Nonlinear State-Space Model with unknown dynamics. The main challenge in this scenario is that the dynamics of the system are often unknown or too complex to model analytically. Traditional approaches might struggle with capturing the nonlinear relationships in such systems. Neural networks offer a powerful solution by learning these complex dynamics directly from data, but incorporating them into a Bayesian framework requires careful integration to maintain probabilistic interpretations and uncertainty quantification. This tutorial demonstrates how to overcome these challenges by combining the flexibility of neural networks with the principled uncertainty handling of probabilistic programming. Specifically, we will utilize the time series generated by the Lorenz system as an example.
# Lorenz system equations to be used to generate dataset
Base.@kwdef mutable struct Lorenz
    dt::Float64
    σ::Float64
    ρ::Float64
    β::Float64
    x::Float64
    y::Float64
    z::Float64
end

# Define the Lorenz dynamics
function step!(l::Lorenz)
    dx = l.σ * (l.y - l.x);         l.x += l.dt * dx
    dy = l.x * (l.ρ - l.z) - l.y;   l.y += l.dt * dy
    dz = l.x * l.y - l.β * l.z;     l.z += l.dt * dz
end

function create_dataset(rng, σ, ρ, β_nom; variance = 1f0, n_steps = 100, p_train = 0.8, p_test = 0.2)
    attractor = Lorenz(0.02, σ, ρ, β_nom/3.0, 1, 1, 1)
    signal       = [Float32[1.0, 1.0, 1.0]]
    noisy_signal = [last(signal) + randn(rng, Float32, 3) * variance]
    for i in 1:(n_steps - 1)
        step!(attractor)
        push!(signal, Float32[attractor.x, attractor.y, attractor.z])
        push!(noisy_signal, last(signal) + randn(rng, Float32, 3) * variance)
    end

    return (
        parameters = (σ, ρ, β_nom),
        signal = signal,
        noisy_signal = noisy_signal
    )
end
create_dataset (generic function with 1 method)rng = StableRNG(999) # dummy rng
variance = 2f0
dataset = create_dataset(rng, 11, 23, 6; variance = variance, n_steps = 200);
The dataset generated above represents the Lorenz system, a well-known chaotic dynamical system. We've created both clean trajectories following the exact Lorenz equations and noisy observations by adding Gaussian noise with variance 2.0. The dataset contains 200 time steps, providing sufficient data to train our neural network model. The parameters used for this Lorenz system are σ=11, ρ=23, and β=6. This noisy dataset will allow us to test our neural network's ability to filter out noise and recover the underlying dynamics.
# Extract first samples from datasets
sample_clean = dataset.signal
sample_noisy = dataset.noisy_signal

# Pre-allocate arrays for better performance
n_points = length(sample_clean)
gx, gy, gz = zeros(n_points), zeros(n_points), zeros(n_points)
rx, ry, rz = zeros(n_points), zeros(n_points), zeros(n_points)

# Extract coordinates
for i in 1:n_points
    # Noisy observations
    rx[i], ry[i], rz[i] = sample_noisy[i][1], sample_noisy[i][2], sample_noisy[i][3]
    # True state
    gx[i], gy[i], gz[i] = sample_clean[i][1], sample_clean[i][2], sample_clean[i][3]
end

# Create three projection plots
p1 = scatter(rx, ry, label="Noisy observations", alpha=0.7, markersize=2, title = "X-Y Projection")
plot!(p1, gx, gy, label="True state", linewidth=2)

p2 = scatter(rx, rz, label="Noisy observations", alpha=0.7, markersize=2, title = "X-Z Projection")
plot!(p2, gx, gz, label="True state", linewidth=2)

p3 = scatter(ry, rz, label="Noisy observations", alpha=0.7, markersize=2, title = "Y-Z Projection")
plot!(p3, gy, gz, label="True state", linewidth=2)

# Combine plots with improved layout
plot(p1, p2, p3, size=(900, 250), layout=(1,3), margin=5Plots.mm)
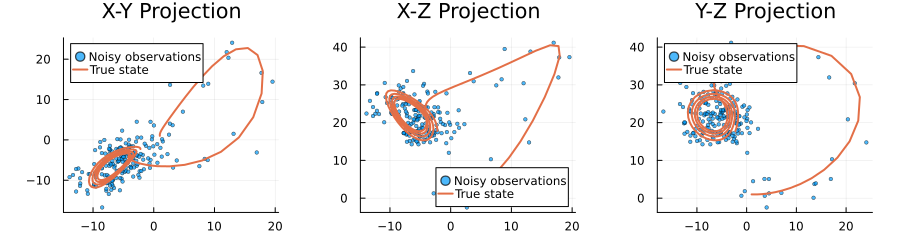
The plots above visualize our noisy Lorenz system dataset from three different perspectives. We can clearly see how the noise (represented by the scattered points) obscures the true underlying dynamics (shown by the solid lines). The Lorenz system's characteristic butterfly-shaped attractor is visible in these projections, though the noisy observations make it challenging to discern the exact trajectory. This visualization highlights the challenge our neural network will face: it must learn to filter out the Gaussian noise (with variance 2.0) and recover the true state of the system at each time step. The X-Y, X-Z, and Y-Z projections each provide a different view of the same 3D dynamical system, helping us understand the full complexity of the dataset.
Bayesian Inference meets Neural Networks
Our objective is to compute the marginal posterior distribution of the latent (hidden) state $x_k$ at each time step $k$, considering the history of measurements up to that time step:
\[p(x_k | y_{1:k}).\]
The above expression represents the probability distribution of the latent state $x_k$ given the measurements $y_{1:k}$ up to time step $k$. The hidden dynamics of the Lorenz system exhibit nonlinearities and hence cannot be solved in the closed form. One manner of solving this problem is by introducing a neural network to approximate the transition matrix of the Lorenz system.
\[\begin{aligned} A_{k-1}=NN(y_{k-1}) \\ p(x_k | x_{k-1})=\mathcal{N}(x_k | A_{k-1}x_{k-1}, Q) \\ p(y_k | x_k)=\mathcal{N}(y_k | Bx_k, R) \end{aligned}\]
where $NN$ is the neural network. The input is the observation $y_{k-1}$, and output is the trasition matrix $A_{k-1}$. $B$ denote distortion or measurment matrix. $Q$ and $R$ are covariance matrices.
Define the Neural Network
We'll use a neural network to approximate the transition matrix of the Lorenz system. The network takes the observation vector as input and outputs a vector that parameterises the diagonal of the transition matrix for the next state. This captures the nonlinear dynamics of the system while keeping inference tractable.
For demonstration purposes we keep the architecture minimal - a single Dense layer with 12 trainable parameters - but everything below generalises to deeper networks, recurrent layers, and so on.
This is the one place where the two libraries genuinely differ, so we write one small function per library. Each returns the same named tuple, which is what lets every later cell be written once:
flat- the trainable parameters as a flat vector,predict(v, dd)- run the network described by parameter vectorvon a batchdd,init_opt(v)/step(state, v, grads)- set up the optimiser and take one update step.
Flux. The layer owns its parameters. Flux.destructure gives us a flat view of them together with a rebuild closure that turns a flat vector back into a layer, and Flux.update! mutates in place.
function flux_backend(rng = StableRNG(1234))
    model = Flux.Dense(3 => 3)

    # `destructure` flattens the parameters held inside the layer and returns a
    # closure that rebuilds a layer from a flat vector.
    flat, rebuild = Flux.destructure(model)

    # Fixed random seed for reproducibility
    rand!(rng, flat)

    return (
        name     = "Flux.jl",
        flat     = flat,
        predict  = (v, dd) -> rebuild(v)(dd),
        init_opt = (v) -> Flux.setup(Flux.Adam(), v),
        step     = (state, v, grads) -> Flux.update!(state, v, grads),
    )
end
flux_backend (generic function with 2 methods)Lux. The layer holds no parameters at all. Lux.setup creates the parameters ps and the non-trainable state st separately, the layer is called as model(x, ps, st) and returns the output alongside a possibly-updated state, and Optimisers.update is functional - it returns new parameters rather than mutating them.
Note the throwaway StableRNG(0) passed to Lux.setup: those initial values are immediately overwritten by rand!(rng, flat) below, so the first 12 random numbers come straight from rng in both backends. That is what makes the two networks start from exactly the same weights.
function lux_backend(rng = StableRNG(1234))
    model = Lux.Dense(3 => 3)

    # Parameters and state live outside the layer. The rng here is a throwaway -
    # the values it produces are overwritten by `rand!` on the next line.
    ps, st = Lux.setup(StableRNG(0), model)
    flat, rebuild = Optimisers.destructure(ps)

    # Fixed random seed for reproducibility - identical to the Flux backend
    rand!(rng, flat)

    return (
        name     = "Lux.jl",
        flat     = flat,
        # A Lux layer is called with (input, parameters, state) and returns
        # (output, new_state); we only need the output here.
        predict  = (v, dd) -> first(model(dd, rebuild(v), st)),
        init_opt = (v) -> Optimisers.setup(Optimisers.Adam(), v),
        step     = (state, v, grads) -> Optimisers.update(state, v, grads),
    )
end
lux_backend (generic function with 2 methods)Both backends start from the same 12 parameters and, given the same parameters, compute the same thing:
flux_nn = flux_backend()
lux_nn  = lux_backend()

let probe = randn(StableRNG(7), Float32, 3, 5)
    println("Same initial parameters: ", flux_nn.flat == lux_nn.flat, " (", length(flux_nn.flat), " of them)")
    println("Same forward pass:       ", flux_nn.predict(flux_nn.flat, probe) ≈ lux_nn.predict(lux_nn.flat, probe))
end
Same initial parameters: true (12 of them)
Same forward pass:       true
Probabilistic Model Specification
Now we'll define our probabilistic state-space model using RxInfer.jl. This model will incorporate the neural network's predictions of the transition matrices. The model consists of two main components: the state transition equation, which uses our neural network to predict how the state evolves, and the observation equation, which relates the hidden state to the measurements. By combining these components, we create a framework that can handle the nonlinear dynamics of the Lorenz system while maintaining computational tractability.
@model function ssm(y, As, Q, B, R)

    x_prior_mean = ones(Float32, 3)
    x_prior_cov  = Matrix(Diagonal(ones(Float32, 3)))

    x[1] ~ MvNormal(mean = x_prior_mean, cov = x_prior_cov)
    y[1] ~ MvNormal(mean = B * x[1], cov = R)

    for i in 2:length(y)
        x[i] ~ MvNormal(mean = As[i - 1] * x[i - 1], cov = Q)
        y[i] ~ MvNormal(mean = B * x[i], cov = R)
    end
end
We set distortion matrix $B$ and the covariance matrices $Q$ and $R$ as identity matrix. We assume that the observation noise is Gaussian with variance 2.0.
Q = diageye(Float32, 3)
B = diageye(Float32, 3)
R = variance * diageye(Float32, 3)
;
Before proceeding with inference, we need a function that extracts the transition matrices $A$ from the network's output. Because both backends expose the same predict, this is written once and works for either.
function get_matrices(predict, v, data)
    dd = hcat(data...)
    As = predict(v, dd)
    return map(c -> Matrix(Diagonal(c)), eachcol(As))
end
get_matrices (generic function with 1 method)Un-trained network
Before network training, we show the inference results for the hidden states:
In this section, we'll demonstrate how our model performs with an untrained neural network. This will serve as a baseline to compare against after training. We expect the inference results to be poor since the untrained network generates random transition matrices that don't capture the true dynamics of the system. The plots below will visualize the true states, noisy observations, and the inferred states for each of the three coordinates in our state space model.
function run_inference(backend, v, data; Q = Q, B = B, R = R)
    return infer(
        model = ssm(As = get_matrices(backend.predict, v, data), Q = Q, B = B, R = R),
        data  = (y = data, ),
        returnvars = (x = KeepLast(), )
    )
end

# Performance before training, using the untrained (randomly initialised) parameters
untrained_flux = run_inference(flux_nn, flux_nn.flat, dataset.noisy_signal)
untrained_lux  = run_inference(lux_nn,  lux_nn.flat,  dataset.noisy_signal)

# The two backends are numerically identical here too, so we only plot one below
println("Untrained results agree: ",
    all(mean(a) ≈ mean(b) for (a, b) in zip(untrained_flux.posteriors[:x], untrained_lux.posteriors[:x])))
Untrained results agree: true# A helper function for plotting
function plot_coordinate(result, i; title = "")
p = scatter(getindex.(dataset.noisy_signal, i), label="Observations", alpha=0.7, markersize=2, title = title)
plot!(getindex.(dataset.signal, i), label="True states", linewidth=2)
plot!(getindex.(mean.(result.posteriors[:x]), i), ribbon=sqrt.(getindex.(var.(result.posteriors[:x]), i)), label="Inferred states", linewidth=2)
return p
end
function plot_coordinates(result)
p1 = plot_coordinate(result, 1, title = "First coordinate")
p2 = plot_coordinate(result, 2, title = "Second coordinate")
p3 = plot_coordinate(result, 3, title = "Third coordinate")
return plot(p1, p2, p3, size = (1000, 600), layout = (3, 1), legend=:bottomleft)
end
plot_coordinates (generic function with 1 method)plot_coordinates(untrained_flux)

As we can see from the plots above, the inference results with an untrained neural network are essentially nonsense. The inferred states (green lines) fail to track the true states (orange lines) and instead produce arbitrary values with large uncertainty bands. This is expected since the untrained neural network generates random transition matrices that don't capture the actual dynamics of the system. The large discrepancy between the inferred and true states demonstrates why proper training of the neural network is necessary to achieve meaningful results.
Training the network
In this part, we use the Free Energy as the objective function to optimize the weights of our neural network. Free Energy is a variational inference objective that balances model fit with complexity. By minimizing Free Energy, we encourage the neural network to learn transition matrices that:
- Accurately predict the next state given the current state (reducing prediction error)
- Maintain appropriate uncertainty in the predictions
- Capture the underlying dynamics of the system without overfitting to noise
The Free Energy is computed by RxInfer.infer(...) itself, so the objective below runs a full inference pass on every call. We differentiate straight through it with ForwardDiff.jl. With only 12 parameters, forward-mode AD is both fast and robust here. Reverse-mode backends such as Enzyme.jl and compile-to-XLA backends such as Reactant.jl are the modern default for pure Lux training, but they do not currently work end-to-end through RxInfer's reactive message-passing engine.
Because the objective only ever sees a flat parameter vector, it too is shared between the two libraries.
# free energy objective to be optimized during training
function make_fe_tot_est(backend, data; Q = Q, B = B, R = R)
    function fe_tot_est(v)
        result = infer(
            model = ssm(As = get_matrices(backend.predict, v, data), Q = Q, B = B, R = R),
            data  = (y = data, ),
            returnvars = (x = KeepLast(), ),
            free_energy = true,
            session = nothing
        )
        return result.free_energy[end]
    end
end
make_fe_tot_est (generic function with 1 method)The training loop is shared as well. The only library-specific step inside it is backend.step, which hides the difference between Flux's in-place update! and Lux/Optimisers' functional update behind a single signature that returns the new optimiser state and the new parameters.
function train(backend, data; num_epochs = 1000)
    fe_tot_est = make_fe_tot_est(backend, data)

    v         = copy(backend.flat)
    opt_state = backend.init_opt(v)

    # Record the objective as training proceeds so the two libraries can be compared
    trace      = Tuple{Int, Float64}[]
    print_each = max(1, num_epochs ÷ 10)
    start_time = time()

    for epoch in 1:num_epochs
        if epoch % print_each == 0
            current_value = fe_tot_est(v)
            push!(trace, (epoch, current_value))
            elapsed   = time() - start_time
            remaining = elapsed / epoch * (num_epochs - epoch)
            println("[$(backend.name)] Epoch $epoch/$num_epochs: Free Energy = $current_value, ETA: $(round(remaining; digits=1)) seconds")
        end
        grads = ForwardDiff.gradient(fe_tot_est, v)
        opt_state, v = backend.step(opt_state, v, grads)
    end

    println("[$(backend.name)] Finished in $(round(time() - start_time; digits=1)) seconds")
    return v, trace
end
train (generic function with 1 method)Now we train the same network twice - once through each library - on the same data, from the same initial weights, with the same optimiser settings and the same AD backend. The following cells run 1000 epochs each, which is sufficient for convergence.
trained_flux_v, flux_trace = train(flux_nn, dataset.noisy_signal; num_epochs = 1000)
[Flux.jl] Epoch 100/1000: Free Energy = 24170.93445802461, ETA: 376.5 secon
ds
[Flux.jl] Epoch 200/1000: Free Energy = 22554.715036790676, ETA: 211.4 seco
nds
[Flux.jl] Epoch 300/1000: Free Energy = 20249.69006438921, ETA: 149.8 secon
ds
[Flux.jl] Epoch 400/1000: Free Energy = 15243.431984240679, ETA: 114.0 seco
nds
[Flux.jl] Epoch 500/1000: Free Energy = 5305.610749796523, ETA: 88.2 second
s
[Flux.jl] Epoch 600/1000: Free Energy = 1975.290362157377, ETA: 67.0 second
s
[Flux.jl] Epoch 700/1000: Free Energy = 1565.4753557001181, ETA: 47.8 secon
ds
[Flux.jl] Epoch 800/1000: Free Energy = 1528.593188360794, ETA: 30.7 second
s
[Flux.jl] Epoch 900/1000: Free Energy = 1515.1280096773944, ETA: 14.9 secon
ds
[Flux.jl] Epoch 1000/1000: Free Energy = 1510.1631271098695, ETA: 0.0 secon
ds
[Flux.jl] Finished in 146.3 seconds
(Float32[-0.0013781044, -0.0037476958, -0.0009489034, 0.0039143777, 0.00010
565781, 0.0046671242, -0.0057990616, -0.015720239, -0.0023217094, 1.1312662
, 1.2965654, 1.0733763], [(100, 24170.93445802461), (200, 22554.71503679067
6), (300, 20249.69006438921), (400, 15243.431984240679), (500, 5305.6107497
96523), (600, 1975.290362157377), (700, 1565.4753557001181), (800, 1528.593
188360794), (900, 1515.1280096773944), (1000, 1510.1631271098695)])
trained_lux_v, lux_trace = train(lux_nn, dataset.noisy_signal; num_epochs = 1000)
[Lux.jl] Epoch 100/1000: Free Energy = 24170.93445802461, ETA: 245.5 second
s
[Lux.jl] Epoch 200/1000: Free Energy = 22554.715036790676, ETA: 153.5 secon
ds
[Lux.jl] Epoch 300/1000: Free Energy = 20249.69006438921, ETA: 115.8 second
s
[Lux.jl] Epoch 400/1000: Free Energy = 15243.431984240679, ETA: 91.3 second
s
[Lux.jl] Epoch 500/1000: Free Energy = 5305.610749796523, ETA: 73.1 seconds
[Lux.jl] Epoch 600/1000: Free Energy = 1975.290362157377, ETA: 56.2 seconds
[Lux.jl] Epoch 700/1000: Free Energy = 1565.4753557001181, ETA: 41.4 second
s
[Lux.jl] Epoch 800/1000: Free Energy = 1528.593188360794, ETA: 27.0 seconds
[Lux.jl] Epoch 900/1000: Free Energy = 1515.1280096773944, ETA: 13.2 second
s
[Lux.jl] Epoch 1000/1000: Free Energy = 1510.1631271098695, ETA: 0.0 second
s
[Lux.jl] Finished in 131.5 seconds
(Float32[-0.0013781044, -0.0037476958, -0.0009489034, 0.0039143777, 0.00010
565781, 0.0046671242, -0.0057990616, -0.015720239, -0.0023217094, 1.1312662
, 1.2965654, 1.0733763], [(100, 24170.93445802461), (200, 22554.71503679067
6), (300, 20249.69006438921), (400, 15243.431984240679), (500, 5305.6107497
96523), (600, 1975.290362157377), (700, 1565.4753557001181), (800, 1528.593
188360794), (900, 1515.1280096773944), (1000, 1510.1631271098695)])
Now let's analyze the results of our neural network training. We'll visualize how well our trained model can infer the true states from noisy observations. The plots below will show the original noisy observations, the true underlying states, and our model's inferred states with confidence intervals. This comparison will help us evaluate the effectiveness of our neural network-based approach in capturing the non-linear dynamics of the system and filtering out noise.
trained_flux = run_inference(flux_nn, trained_flux_v, dataset.noisy_signal)
trained_lux  = run_inference(lux_nn,  trained_lux_v,  dataset.noisy_signal)

plot_coordinates(trained_flux)
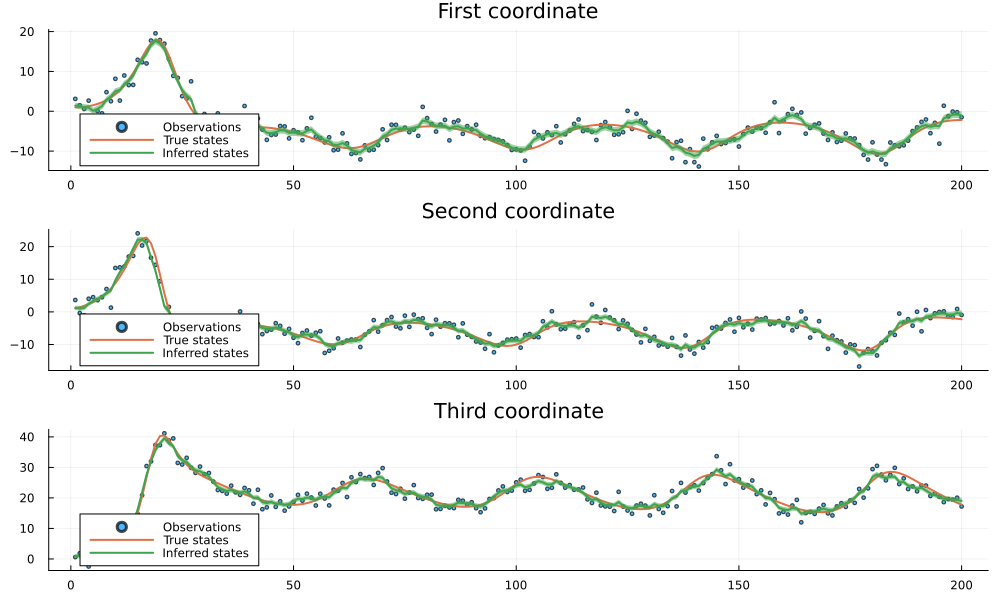
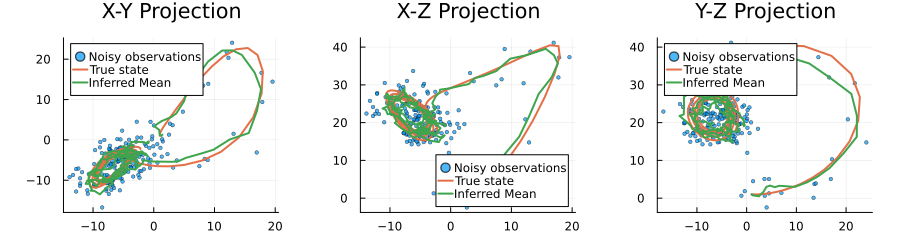
The results demonstrate the effectiveness of our neural network-based state-space model approach. Despite the significant noise present in the observations (shown as scattered points), our model successfully identifies the underlying hidden signal (shown by the inferred states line). The close alignment between the inferred states and the true states across all three coordinates indicates that the trained neural network has effectively learned the non-linear dynamics of the system. The narrow confidence bands (shown as ribbons) around the inferred states further suggest high confidence in the predictions. This example illustrates how combining neural networks with probabilistic state-space models can provide robust inference in scenarios with complex dynamics and noisy observations.
Comparing the two libraries
Both runs started from the same weights and followed the same optimisation recipe, so we can check directly how far apart they ended up - in the learned parameters, in the free energy trace, and in the inferred trajectories.
param_diff = maximum(abs.(trained_flux_v .- trained_lux_v))
fe_diff    = maximum(abs(f[2] - l[2]) for (f, l) in zip(flux_trace, lux_trace))

flux_means = mean.(trained_flux.posteriors[:x])
lux_means  = mean.(trained_lux.posteriors[:x])
state_diff = maximum(maximum(abs.(f .- l)) for (f, l) in zip(flux_means, lux_means))

println("Largest difference in trained parameters:  ", param_diff)
println("Largest difference in free energy trace:   ", fe_diff)
println("Largest difference in inferred states:     ", state_diff)
println()
println("Final free energy - Flux.jl: ", last(flux_trace)[2])
println("Final free energy - Lux.jl:  ", last(lux_trace)[2])
Largest difference in trained parameters:  0.0
Largest difference in free energy trace:   0.0
Largest difference in inferred states:     0.0

Final free energy - Flux.jl: 1510.1631271098695
Final free energy - Lux.jl:  1510.1631271098695
p_fe = plot(first.(flux_trace), last.(flux_trace),
label = "Flux.jl", linewidth = 3, alpha = 0.7,
title = "Free energy during training", xlabel = "Epoch", ylabel = "Free energy")
plot!(p_fe, first.(lux_trace), last.(lux_trace),
label = "Lux.jl", linewidth = 2, linestyle = :dash)
p_x = scatter(getindex.(dataset.noisy_signal, 1), label = "Observations", alpha = 0.4, markersize = 2,
title = "First coordinate: both libraries against the true state")
plot!(p_x, getindex.(dataset.signal, 1), label = "True state", linewidth = 2)
plot!(p_x, getindex.(flux_means, 1), label = "Inferred (Flux.jl)", linewidth = 3, alpha = 0.7)
plot!(p_x, getindex.(lux_means, 1), label = "Inferred (Lux.jl)", linewidth = 2, linestyle = :dash)
plot(p_fe, p_x, size = (1000, 600), layout = (2, 1), legend = :bottomleft)
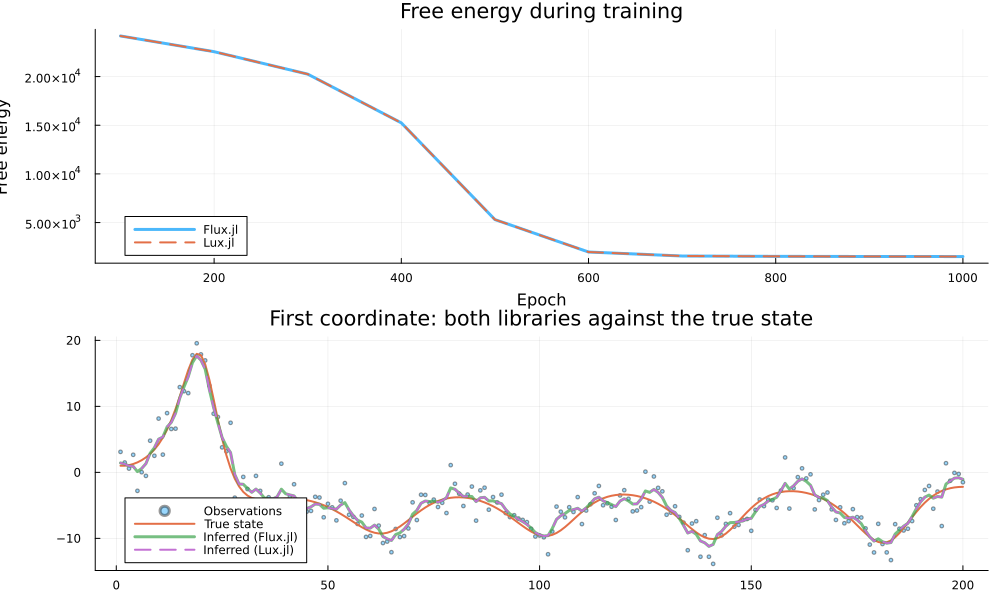
The two curves lie exactly on top of each other. The differences printed above are not merely small - they are all exactly zero: the trained parameters, the free energy at every recorded epoch, and the inferred states agree bit for bit. That is the expected outcome once the two runs share initial weights, data, optimiser settings and AD backend, and it is worth seeing explicitly. Underneath, both libraries update parameters through Optimisers.jl with the same Adam defaults, so there is no numerical daylight between them at all.
What differs is the API you write against.
| Flux.jl | Lux.jl | |
|---|---|---|
| Where parameters live | inside the layer object | outside, in a separate ps |
| Creating a layer | Flux.Dense(3 => 3) | Lux.Dense(3 => 3) plus Lux.setup(rng, model) |
| Forward pass | model(x) | model(x, ps, st), returns (y, new_st) |
| Flattening parameters | Flux.destructure(model) | Optimisers.destructure(ps) |
| Optimiser update | Flux.update!(state, ps, grads), in place | Optimisers.update(state, ps, grads), returns new values |
Flux's in-place style is compact and familiar if you have used PyTorch. Lux's functional style keeps parameters explicit, which is what makes them straightforward to hand to an arbitrary automatic-differentiation pipeline - as we did here by differentiating an entire RxInfer inference pass with ForwardDiff.
A practical note on naming: because both libraries export Dense, setup and destructure, they cannot both be brought in with using in the same session. Importing them qualified, as at the top of this notebook, is the way to use them side by side.
ix, iy, iz = zeros(n_points), zeros(n_points), zeros(n_points)

inferred_mean = mean.(trained_flux.posteriors[:x])

# Extract coordinates
for i in 1:n_points
    # Inferred mean
    ix[i], iy[i], iz[i] = inferred_mean[i][1], inferred_mean[i][2], inferred_mean[i][3]
end

# Create three projection plots
p1 = scatter(rx, ry, label="Noisy observations", alpha=0.7, markersize=2, title = "X-Y Projection")
plot!(p1, gx, gy, label="True state", linewidth=2)
plot!(p1, ix, iy, label="Inferred Mean", linewidth=2)

p2 = scatter(rx, rz, label="Noisy observations", alpha=0.7, markersize=2, title = "X-Z Projection")
plot!(p2, gx, gz, label="True state", linewidth=2)
plot!(p2, ix, iz, label="Inferred Mean", linewidth=2)

p3 = scatter(ry, rz, label="Noisy observations", alpha=0.7, markersize=2, title = "Y-Z Projection")
plot!(p3, gy, gz, label="True state", linewidth=2)
plot!(p3, iy, iz, label="Inferred Mean", linewidth=2)

# Combine plots with improved layout
plot(p1, p2, p3, size=(900, 250), layout=(1,3), margin=5Plots.mm)
This example was automatically generated from a Jupyter notebook in the RxInferExamples.jl repository.
We welcome and encourage contributions! You can help by:
- Improving this example
- Creating new examples
- Reporting issues or bugs
- Suggesting enhancements
Visit our GitHub repository to get started. Together we can make RxInfer.jl even better! 💪
This example was executed in a clean, isolated environment. Below are the exact package versions used:
For reproducibility:
- Use the same package versions when running locally
- Report any issues with package compatibility
Status `/tmp/jl_9n7wDE/Project.toml`
⌅ [587475ba] Flux v0.14.25
⌅ [f6369f11] ForwardDiff v0.10.39
⌃ [b2108857] Lux v1.2.3
⌅ [3bd65402] Optimisers v0.3.4
  [91a5bcdd] Plots v1.41.7
  [86711068] RxInfer v5.5.2
  [860ef19b] StableRNGs v1.0.4
  [37e2e46d] LinearAlgebra v1.12.0
Info Packages marked with ⌃ and ⌅ have new versions available. Those with ⌃ may be upgradable, but those with ⌅ are restricted by compatibility constraints from upgrading. To see why use `status --outdated`